

Design principles
The architecture is shaped by a small set of decisions that hold across every layer.Events are the source of truth
Every billing outcome is derived from raw usage events. Those events are persisted redundantly and retained for replay, so any downstream state can be rebuilt from first principles.
Redundancy at every hop
No single component failure causes data loss. Each stage of the pipeline has an independent durable store that absorbs the failure of the stage after it.
Region isolation by default
Every component is region-restricted. Data never leaves the region your deployment runs in.
System architecture
The platform is fully containerized. A single codebase runs in three modes — API, Consumer, and Background Worker — behind a load balancer, with a private data tier (multi-AZ) and a set of external components for analytics, orchestration, and webhook delivery. Only the API service is exposed to the internet. It sits behind an Application Load Balancer and a WAF in public subnets; every database, broker, and cache lives in private subnets, across multiple availability zones, with no inbound internet route.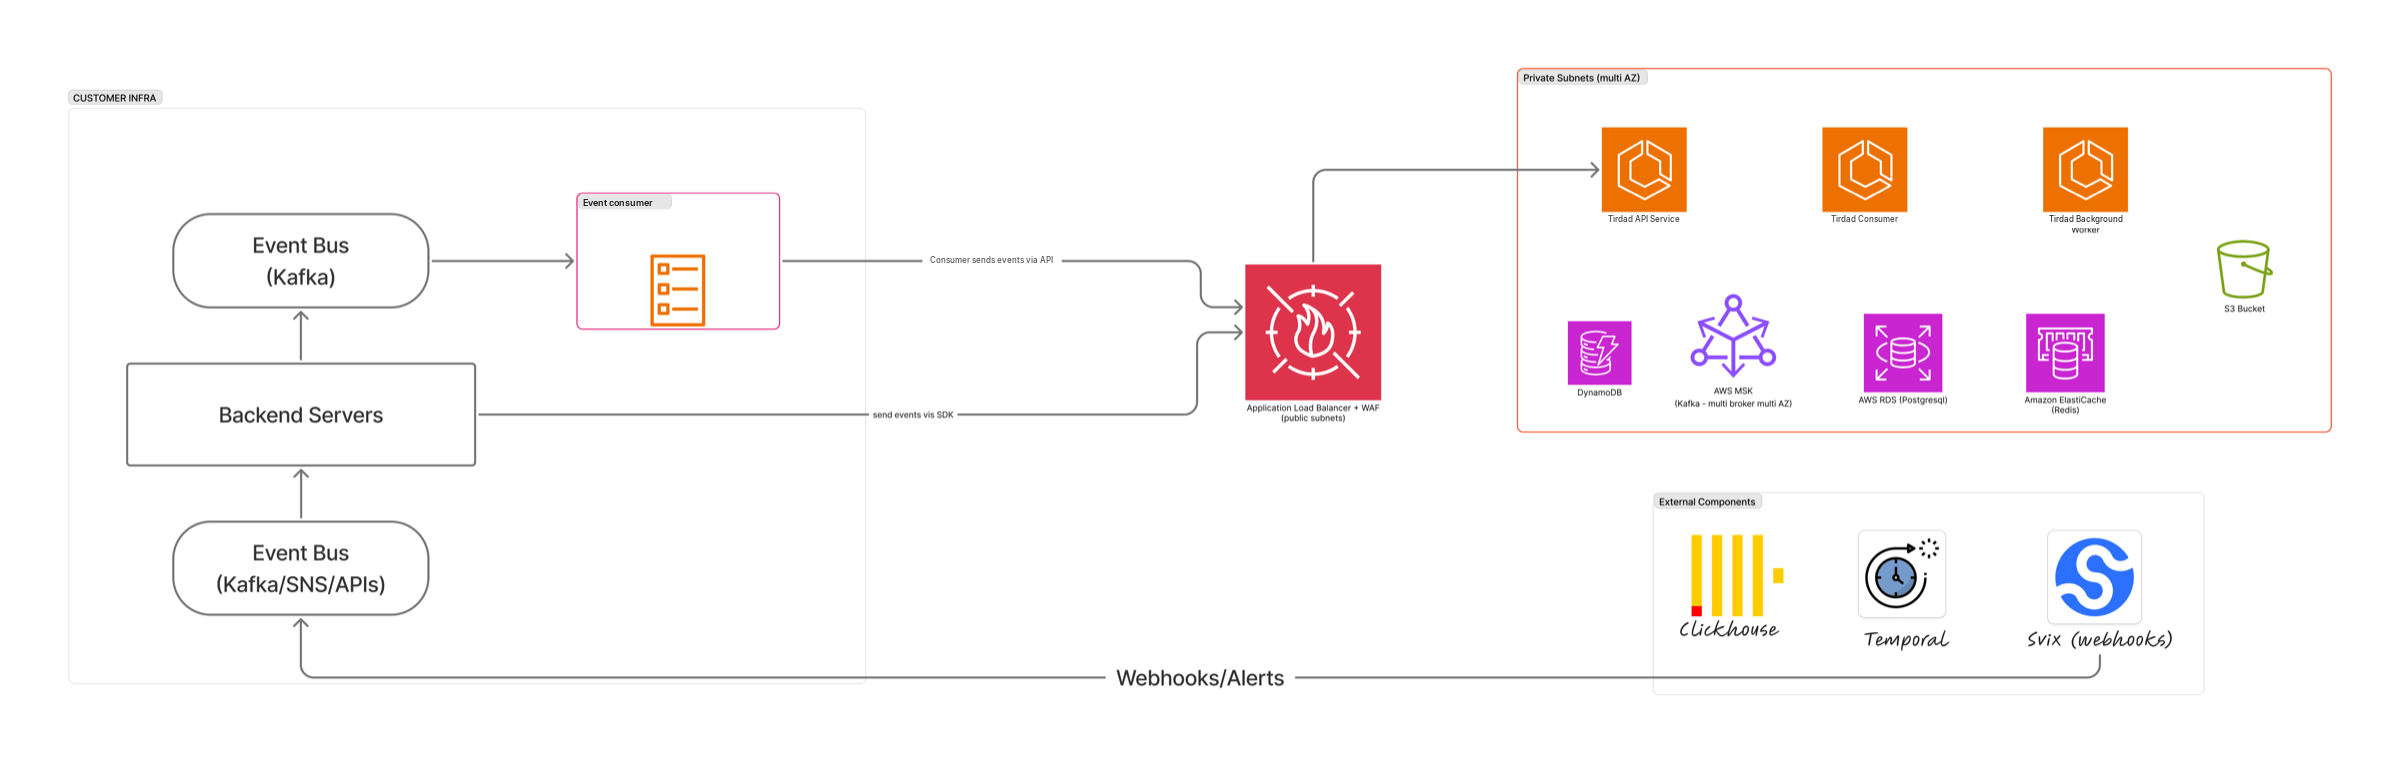
Runtime services
All three services are the same image, started in different roles. This keeps deployment, versioning, and operational tooling uniform.Data stores
Each store is chosen for one job and isolated to it. The one managed-cloud service below — DynamoDB — is optional and used only in Tirdad Cloud.DynamoDB is the only managed-cloud component in the architecture, and it is entirely optional. Tirdad uses it in Tirdad Cloud as the most resilient form of data-redundancy store. Enterprise deployments do not include it and require no cloud-specific component — durability is already guaranteed by Kafka’s replayable log, the SDK’s retries, and the S3 degraded-mode fallback.
Event ingestion pipeline
Ingestion is the most infrastructure-heavy part of the system, because it is the part that must never lose data. Everything downstream — balances, invoices, analytics, reconciliation — is reconstructable as long as the events survive.Ingestion modes
You choose how events reach Tirdad based on how your systems are already built.SDK
Server-side SDKs in all popular languages send events directly. The SDK runs in sync mode with configurable retries and fallback handling built in.
Direct API
For systems that prefer to call Tirdad directly, every ingestion path is also a plain authenticated REST endpoint.
Ingestion flow
The receive path is deliberately lightweight. The API performs only static validation — a well-formed payload on an authenticated endpoint — then writes the event to Kafka, the durable backbone, before acknowledging. In Tirdad Cloud the API additionally writes to DynamoDB as an optional redundancy buffer; Enterprise deployments rely on Kafka’s replayable log alone. Heavier work (enrichment, aggregation, ClickHouse writes) happens asynchronously off the Kafka stream, so a spike in volume never slows the acknowledgement path.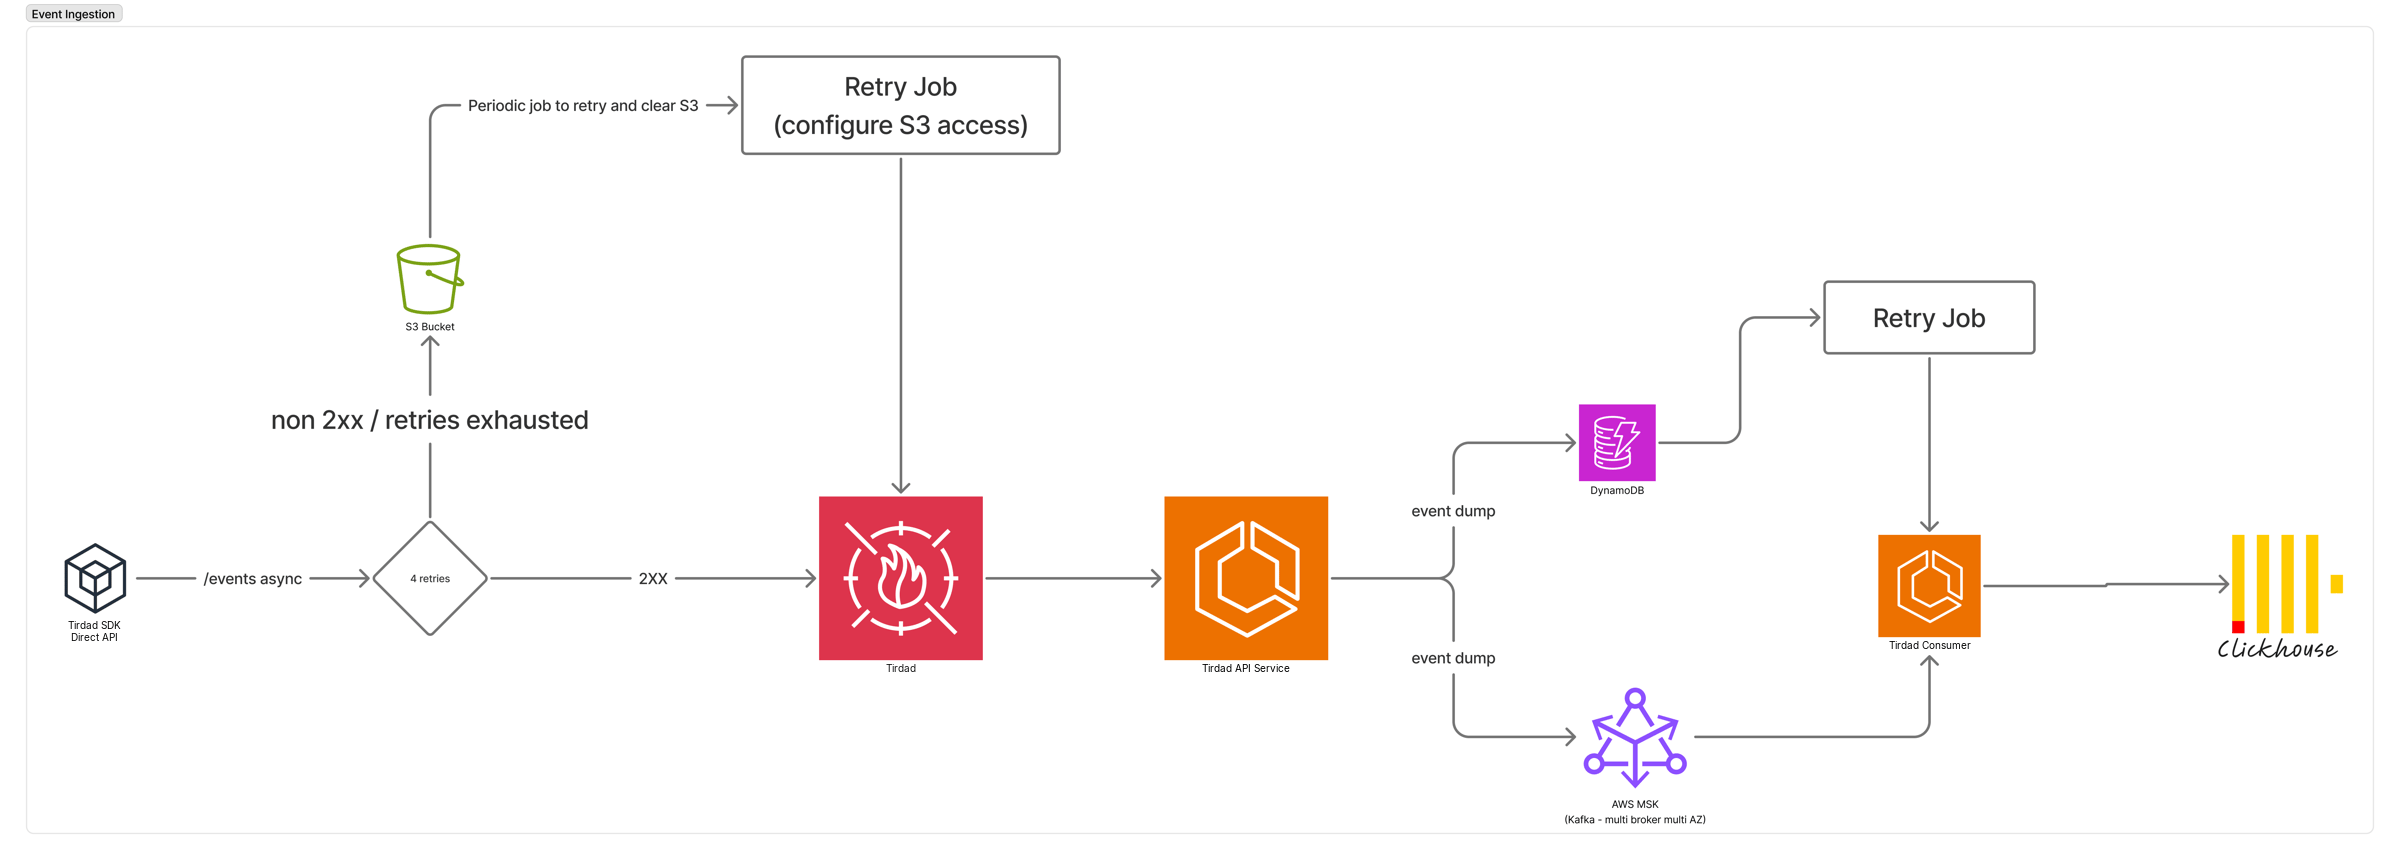
Reliability and failure modes
The pipeline is designed so that the failure of any one component degrades gracefully and loses nothing. Each stage is backed by an independent durable store that absorbs the failure of the stage after it.Data recovery and replay
Because events are the currency of the system, they are retained well beyond their processing lifetime. In Tirdad Cloud, events held in DynamoDB are retained for up to one year and then archived to S3, giving point-in-time replay across the entire window; Enterprise deployments achieve the same replay from Kafka’s retained log and S3 archival. If any downstream store is lost or corrupted, it can be rebuilt by replaying the retained events — no derived state is ever the only copy of anything.The degraded-mode S3 fallback and its retry jobs are an opt-in, per-customer configuration deployed for enterprise workloads. It requires granting Tirdad server-to-server read access to the bucket.
Real-time balances and alerting
The most latency-sensitive question in usage billing is does this customer have balance to perform this action? Tirdad answers it without forcing you onto its critical path.How balances are computed
Balances are never stored as a separate mutable number — they are derived from usage in ClickHouse. Every incoming event is rolled up into materialized views and pre-aggregated tables, so the current balance is a fast aggregation query rather than a running counter that can drift. The fetch-balance API lets the caller decide the freshness it needs. Rather than a fixed server-side TTL, the caller specifies a maximum acceptable age per request: if the cached value is within that age it is returned immediately from cache; if it is staler, the value is recomputed from ClickHouse. Critical surfaces — the billing page, the customer portal — always read the live value.Push-based alerts
Most customers never query Tirdad in their hot path at all. Every event enqueues a per-customer aggregation that fires at most once per customer per minute, and that single trigger drives:- Low-balance alerts
- Auto top-ups
- Entitlement-exhaustion alerts
has_balance flag per customer in their own Redis, updated from these alerts, and gate actions on that flag. Tirdad is never in the critical path of the decision.
Balance freshness
Balance freshness describes how recently ingested usage is reflected in a returned balance. It depends on ingestion, processing, and cache configuration. Any guaranteed reconciliation window is defined in your agreement.Service-level agreements
The API service is the internet-facing component customers depend on for reporting usage and checking entitlements and wallet balances. Availability, response latency, and balance freshness describe different aspects of that service and should be evaluated separately. Availability commitments, support tiers, and service credits are defined in your agreement and applicable order form. Enterprise agreements may specify custom service levels.Availability
Availability is measured per region in five-minute intervals as
1 − (failed requests ÷ total requests) against the API service, aggregated over a calendar month. Failed requests are server-side 5xx responses originating from Tirdad. The calculation excludes scheduled maintenance announced in advance, errors caused by client misuse (4xx, invalid payloads, throttling), and disruption outside Tirdad’s control. The contractual SLA and any associated service credits are defined in your agreement.
Latency targets
The balance check is the path most customers gate actions on. The ingestion target reflects the lightweight receive path described above: the API acknowledges after the durable write and defers enrichment off the Kafka stream. Response latency is distinct from balance freshness — how recently usage is reflected in the returned number — which is governed by the balance freshness above, and can be tightened to sub-minute on Enterprise deployments.
Data residency
Every component of a deployment is restricted to the region it runs in, and the managed dependencies are configured against the matching regional cloud. Data is processed and stored only within that region. Enterprise deployments run in the region you choose, which lets them satisfy residency requirements without bespoke engineering.Observability
The entire platform is OpenTelemetry-native and streams both traces and logs. You can point it at your own OTel-compatible provider, so Tirdad telemetry lands alongside the rest of your stack rather than in a silo. For enterprise deployments, the internal dashboards are shared as exportable definitions so you start with the same operational view the Tirdad team uses.Analytics and reconciliation
Billing systems live or die on whether their numbers can be independently verified. Tirdad exposes its data at several levels so you can reconcile however you prefer.Direct query access
Direct query access
ClickHouse (real-time event data) and PostgreSQL (subscriptions, invoices, configuration) are exposed over read-only connections to a BI tool such as Metabase, giving you full SQL access to build any reconciliation or analytics workflow.
Analytics API
Analytics API
A summarized customer-level view — usage, wallet balance, and the subscription, price, meter, feature, and line item every figure derives from — available out of the box without standing up a BI stack. The same API powers the built-in customer portal.
Scheduled exports
Scheduled exports
Hourly exports of processed event rows, fully enriched with their meter, feature, and price mappings, delivered to your S3 as CSV or JSON for ingestion into your own systems.
Full CRUD API surface
Full CRUD API surface
Every entity — meters, prices, features, customers, and more — exposes complete CRUD APIs. Any workflow Tirdad runs internally can be rebuilt on your side.
Deployment models
The same architecture is delivered two ways, with no divergence in code between them.Cloud
Fully managed SaaS. Tirdad operates the entire stack — sign up and start billing with no infrastructure to run.
Enterprise
A single-tenant deployment in your own infrastructure or a dedicated environment in your preferred region, operated by Tirdad to an agreed SLA. Identical architecture, isolated to you.